Learning how to use schema markup for AI search matters now because good writing alone no longer gets a page found. Not too long ago, good writing was more than enough for your text to pop up in someone’s search. If your page was able to answer a question well and in a clear, concise way, readers were generally satisfied, as they got what they needed. The reader was rewarded, your page saw traffic, and everyone was able to benefit. Today, you need to learn how to use schema markup for AI search to achieve the same.
The reason is that search engines and AI systems don’t operate the same way a human reader does. They can benefit from structured data, which can help them understand information that they see. Writing something worth reading is no longer enough, since content useful to human eyes might just confuse AI, causing it to move past it instead of incorporating it into its own answer. LLMs also need plenty of context, or they might mix up facts or provide half-hallucinated, unsupported answers.
What Actually Makes a Page Machine-Readable?
To ensure that search engines and AI systems can interpret a page correctly, you need to understand schema markup best practices for AI search.
Entity Identifiers: @id and sameAs
Imagine AI trying to read a page that talks about Apple. Does it mean the technology company or the fruit? AI could use structured data to better understand the difference. The @id property gives the entity in question - in this case, Apple - a unique identifier in the dataset. This allows other information to reference the same entity, allowing the AI and search engines to understand what the text is talking about more clearly.
Then, there is the sameAs property, which links it to external pages that talk about the same subject, for example, the company’s official profile. These properties allow you to create relationships between entities and help the AI understand it. Note that they are still only as reliable as the information they describe. If the identifiers are not correct, this can create confusion for LLMs rather than make things clearer for them. This is the simplified explanation of how schema markup for AI search visibility works.
Context Blocks and Micro-Chunking
But, how do AI search engines process schema markup during retrieval? AI retrieval systems often divide pages into smaller chunks and passages. These get converted into numbers called vector embeddings, and they help identify content that’s relevant to the user’s question.
An embedding captures the content it receives, but the problem is that it doesn’t get the context that accompanied the relevant information on the original page. For example, if the user asks about a company’s refund policy which appears in one paragraph, while eligibility restrictions appear later in the text, a system may only retrieve the first passage. While the information is accurate, the answer is not complete.
Authorship and Entity Verification
One big question that needs answering when fetching content from the internet is who created it, and why should the reader trust them. That’s where Google’s E-E-A-T framework gets into play, addressing Experience, Expertise, Authoritativeness, and Trustworthiness. The current edition, dated 11 September, 2025, in force through the May 2026 core update, confirms E-E-A-T is still the active framework, and it isn’t a ranking factor or score but a quality lens informing rater guidelines.
Essentially, this is why it’s important for content to come from a trusted and reputable source, and in turn, it’s why one must establish their page as a reputable source in order for content to be retrieved from it.
Google’s own Search Central documentation states plainly: “Don’t mark up content that is not visible to readers of the page… Don’t add structured data about information that is not visible to the user, even if the information is accurate,” and it notes that non-compliance “can prevent syntactically correct structured data from being displayed or possibly cause it to be marked as spam.”
Publishers can support these qualities through accurate author biographies, relevant credentials, transparent sourcing, and clear identification of the organization that provided the content. Structured data can connect articles to authors and publishers, but it is still limited, and it cannot create real expertise or credibility.
For example, an article can use JSON-LD structured data to identify its author as a Person, give that person a unique identifier using the @id property, and link to a verified profile using sameAs. Think of it as a machine-readable author reference, where the article identifies who wrote it, while the external profile helps distinguish the writer from someone else who happens to share the same name. The information should match the visible page and point to relevant profiles.
DOM-to-Schema Alignment
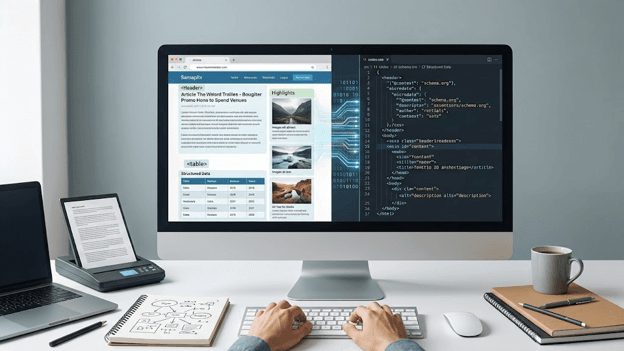
Structured data schema markup for AI search describes a page in a format machines can understand, while the Document Object Model (DOM) represents its underlying webpage structure.
For publishers, that means having to validate both the code and its accuracy against the rendered page. Machine readability depends not only on providing structured information, but on ensuring that it faithfully represents what readers can see, in line with Google’s instructions. In case of a mismatch, the information doesn’t just get quietly ignored, but it could possibly be flagged as spam.
Making Structured Information Work in Practice
Structured information may be crucial, but it is only useful when it’s regularly maintained. Pages require checks and clear formatting so both readers and AI can understand them. You must also maintain realistic expectations about what schema can achieve.
Audit Metadata and Validate It Regularly
You cannot just set the metadata up once and forget about it. Instead, you need teams that can do regular audits, perhaps once a month or even once per quarter. During these audits, they should identify pages with missing schema or other issues like incorrect entity references and outdated details.
They can even use automated validators, which are useful in picking up on syntax errors and missing properties, while manual checks can be reserved to ensure that the provided information is still accurate.
For automated validation, use Google’s Rich Results Test, which can let you check whether markup is eligible for supported rich results. Schema.org Validator can be used to inspect its structure against the Schema.org vocabulary. These tools can be quite useful for catching implementation problems. Just note that passing validation doesn’t guarantee success at reaching high ranks.
Ahrefs ran the most rigorous available test: 1,885 pages that added JSON-LD schema (August 2025 to March 2026) were compared against 4,000 matched control pages. Pages already cited by AI were roughly three times more likely to already carry schema, but adding schema to a page produced no statistically significant citation lift in their controlled test. In fact, AI Overviews citations actually dropped slightly, according to the data.
A separate, less rigorous AccuraCast analysis of 2,000 prompts and 9,000 citation sources found 81% of AI-cited pages carry some schema vs. 19% with none. What this suggests is that schema is correlated with AI citation, but it doesn’t act as a guaranteed booster.
Structure Content for Two Audiences
Give important sections a direct opening sentence that answers the question literally, and then follow it with an explanation that supports the initial answer. You can also use a simple table to make important information stand out so it’s easier for AI to spot it and retrieve it.
For example, a payment platform could create a page where it lists all supported currencies and processing times in a table, and accompany it by natural prose to explain any fees or restrictions. That way, machines can easily find the most important details that the user needs to know without having to read through a wall of text that carries no relevance to their question.
Research has proven that there is value in combining structured relationships with text retrieval. A paper published in 2025 titled KG-Infused RAG: Augmenting Corpus-Based RAG with External Knowledge Graphs reported improvements over conventional RAG across five question-answering benchmarks. The MultiHal study also explored knowledge-graph grounding as a way to evaluate and mitigate hallucinations.
The findings suggest that structured retrieval is a promising way to improve factual grounding. It should be noted, however, that they do not prove that adding website schema alone will lead to the same results.
Conclusion
A page can be well written and accurate and still be passed over because a machine can't tell what it's about. Markup that doesn't match the page can do worse: Google may stop showing it, or treat it as spam. This is simply how machines read the internet, making it the new reality for all those who want to publish useful content and have it seen and retrieved by AI.
Note that structured data doesn’t guarantee better rankings. The content still has to be solid; no schema implementation can help if the information posted doesn’t contain actual worth. The answer is to combine both worlds into one and write for actual people, but structure information for machines. And, of course, regularly check that the information is accurate and that the two are aligned.